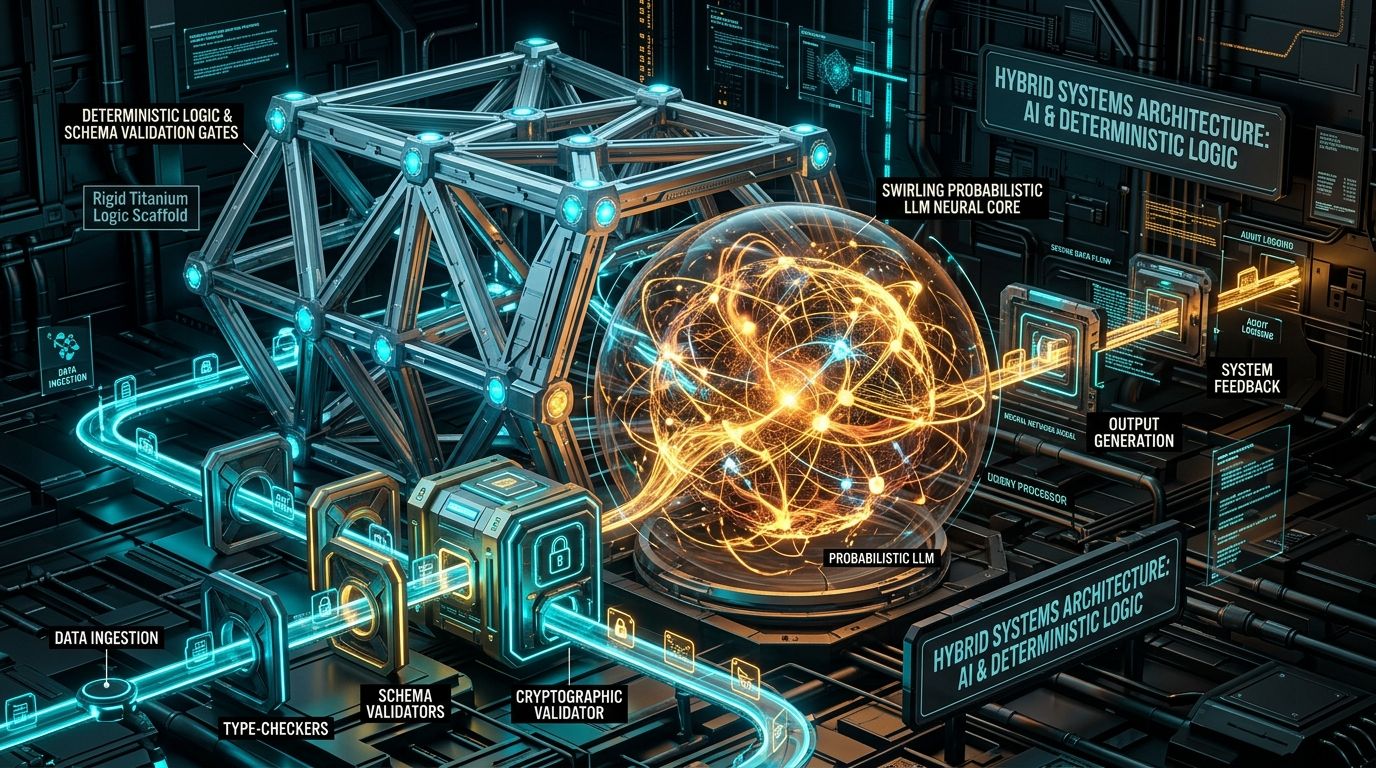
Imagine you are building a modern PC configuration assistant. A user enters their proposed hardware parts into your web interface: an AMD Ryzen 7 7800X3D CPU, an ASUS ROG Strix B650E-F motherboard, 32GB of Corsair Vengeance DDR5 memory, an NVIDIA GeForce RTX 4080 Super graphics card, a Corsair RM850x power supply, and a 2TB NVMe SSD. In the naive architecture embraced by hundreds of generative AI startups today, the backend packages these six component strings into a single prompt and dispatches it directly to a foundation model: "Rate this PC build from 1 to 10 and tell the user whether all components are compatible." Two seconds later, the model outputs a confident response: "Overall Rating: 8.7/10. All components are compatible." It sounds impressive. But ask yourself five fundamental software engineering questions: Why 8.7? Would the exact same hardware configuration receive an 8.7 tomorrow morning? Does the motherboard's physical VRM layout or PCIe lane distribution actually accommodate that specific GPU clearance? What does "8.7" mathematically represent in terms of thermal headroom, component balance, or wattage efficiency? Could a slightly rephrased prompt or an upstream model checkpoint update suddenly demote the build to a 7.4? By asking an LLM to decide compatibility and compute an overall score, the system has committed the cardinal sin of software architecture: it has delegated authoritative facts, mathematical formulas, and deterministic rules to a probabilistic text predictor. The foundational law of reliable systems engineering is clear: If the system already knows the rule, the LLM should not have to guess it. Use code for what you know. Use AI for what you need to interpret.
1. The Fallacy of the All-Knowing Model: Why Probabilistic Systems Fail at Deterministic Rules
In our exploration of AI Agents vs Traditional Automation, we established that autonomous agent loops are designed for semantic uncertainty, while deterministic scripts own certainty. In How to Add AI to a SaaS Product Without Making AI the Entire Product, we proved that AI must exist as a subordinated capability within SaaS infrastructure rather than replacing transactional databases and business logic.
Now, we must confront the most pervasive design failure in enterprise AI engineering: substituting model inference for explicit business rules.
When an engineering team builds a feature entirely on top of an LLM, they are treating a probabilistic neural network as a database, a calculator, an authorization firewall, and a state machine simultaneously. A Large Language Model does not possess an internal relational database of hardware specifications, inventory counts, or corporate pricing matrices. It does not calculate mathematical formulas using arithmetic logic units; it samples token distributions based on statistical associations learned during pre-training.
When you ask an LLM: "Is a DDR4 RAM stick compatible with an AM5 motherboard?", the model might answer correctly 99 out of 100 times because the text "AM5 only supports DDR5" appears thousands of times in its training corpus. But on the 100th invocation—perhaps because of a subtly altered system prompt, a temperature setting above zero, or extraneous user conversational context—the model can output: "Yes, DDR4 will work with appropriate BIOS settings."
In software engineering, a compatibility check cannot have a 1% failure rate. A customer who purchases $800 worth of incompatible physical hardware because an AI hallucinated compatibility will demand an immediate refund and lose all trust in your platform.
PC Build Rating: Naive LLM Delegation vs Production Hybrid Engineering
Contrasting a fragile, probabilistic black box against an auditable, constraint-first pipeline
Delegating Rules to the LLM
- 1. Raw User Input: Unstructured component strings passed straight from UI to prompt template.
- 2. Monolithic Prompt: "Check compatibility, calculate score from 1-10, and explain tradeoffs."
- 3. Probabilistic Hallucination: Model guesses socket compatibility, invents an arbitrary decimal score (8.7/10), and fabricates missing BIOS facts.
- 4. Unauditable Output: UI displays model text directly. Zero database checks, zero physical validation, zero reproducibility.
Deterministic Engine + AI Layer
- 1. Component Normalization: Input mapped to authoritative hardware database IDs (CPU, GPU, Motherboard, RAM, PSU).
- 2. Deterministic Compatibility Engine: Hard rules verify socket (AM5), RAM generation (DDR5), PCIe clearance, and PSU wattage calculations in code.
- 3. Explicit Scoring Engine: Computes transparent dimensions (Workload Fit, Balance, Thermal Headroom) via versioned mathematical methodology.
- 4. AI Narrative Synthesis: LLM receives structured evidence packet: explains strengths, bottlenecks, and upgrade tradeoffs without guessing facts.
2. Rebuilding the System: The Deterministic Engine + AI Layer
Let us examine how a production-grade engineering team rebuilds the PC configuration assistant using rigorous separation of concerns. Instead of asking the model to do everything, the application constructs a layered pipeline:
- Input Normalization: When the user selects or types a component, the application resolves the raw string against a verified catalog database:
AMD Ryzen 7 7800X3Dmaps to catalog recordcpu_am5_7800x3d, which contains hard specifications:socket: "AM5",tdp_watts: 120,memory_type: ["DDR5"],integrated_graphics: true. - Deterministic Compatibility Engine: A set of pure TypeScript or Python functions evaluates known physical and electrical rules:
motherboard.socket === cpu.socket(AM5 === AM5 $\rightarrow$ PASS)motherboard.supported_memory_types.includes(ram.generation)(DDR5 $\rightarrow$ PASS)psu.rated_wattage >= (cpu.tdp_watts + gpu.tdp_watts + 150)(850W >= 570W $\rightarrow$ PASS)gpu.length_mm <= case.max_gpu_clearance_mm(If case data is missing $\rightarrow$ UNKNOWN)
- Explicit Scoring Engine: The application calculates an objective, versioned score (e.g.
score_v1) based on defined product methodology:// Conceptual scoring methodology in deterministic application code export function calculateBuildScore(build: NormalizedBuild): BuildScoreResult { const compatibilityScore = evaluateHardConstraints(build); // Must be 100% to pass if (!compatibilityScore.passed) { return { overall: 0, status: "INCOMPATIBLE", details: compatibilityScore.errors }; } const workloadScore = computeWorkloadFitness(build.gpu, build.cpu, "1440p_gaming"); // 28/30 const balanceScore = computeGpuCpuBalanceRatio(build.gpu, build.cpu); // 24/25 const upgradeFlexibility = evaluatePlatformLongevity(build.motherboard); // 18/20 const powerHeadroom = computePowerEfficiencyCurve(build.psu, build.estimatedDrawWatts); // 12/15 const overall = workloadScore + balanceScore + upgradeFlexibility + powerHeadroom; // 82/100 return { overall, breakdown: { workloadScore, balanceScore, upgradeFlexibility, powerHeadroom } }; } - AI Contextual Analysis: Only after the deterministic engine has computed the verified compatibility checks and the breakdown scores does the system invoke an LLM. The model is passed the exact calculation results in an immutable structured payload: "The build scored 82/100. Workload fitness is 28/30 for 1440p gaming, but upgrade flexibility is constrained by the B650 motherboard's limited secondary M.2 lanes." The AI is tasked with explaining the results in natural language, suggesting contextual optimizations, and highlighting tradeoffs.
The result is night and day: Facts originate from the code. Interpretation originates from the AI. If a customer asks why their build scored 82, you can show them the exact formula, the input metrics, and the rule execution trace. The AI's job is to translate engineering data into clear human prose, not to invent reality.
The Critical Nuance: Hardware Compatibility Is Not Always Simple
Before leaving the PC example, an essential engineering safeguard must be articulated: do not assume every real-world compatibility question can be resolved with simplistic binary rules.
In the real world, hardware compatibility can depend on subtle, messy variables:
- Does the motherboard support the CPU out-of-the-box, or does it require a specific minimum BIOS firmware revision?
- Does a towering air cooler physically clear high-profile RGB RAM heat-spreaders in the first memory slot?
- Does a triple-fan GPU sag and block the lower SATA ports on a micro-ATX chassis?
When reliable structured data exists for these variables, encode them into deterministic rules. But when data is incomplete, the system must never allow an AI to fabricate certainty. This leads directly to the foundational concept of the UNKNOWN state.
3. The "UNKNOWN" State: Why Real Systems Need Three-Valued Logic
Traditional programming teaches developers to think in binary boolean values: TRUE or FALSE. Did the check pass? true. Is the user an admin? false.
In modern AI systems engineering, binary logic is fundamentally inadequate. Production systems must operate under three-valued logic:
- TRUE (Verified): The system possesses authoritative data confirming the rule is satisfied (e.g. Socket AM5 matches Socket AM5).
- FALSE (Violated): The system possesses authoritative data confirming a rule violation (e.g. DDR4 RAM installed in a DDR5 motherboard).
- UNKNOWN (Insufficient Information): The system does not possess enough structured telemetry or documentation to determine the answer with certainty.
The catastrophic failure mode of generative AI applications is turning Zone 3 (UNKNOWN) into Zone 2 (PROBABILISTIC) just so the model can guess an answer.
If your database does not know the exact BIOS version installed on a factory motherboard, the correct system behavior is to output:
Socket Compatibility: VERIFIED (AM5)
RAM Type: VERIFIED (DDR5)
BIOS Firmware Support: UNKNOWN (Requires verification of factory BIOS version prior to Ryzen 7 7800X3D boot)
When you present this structured reality to the AI, the model can inform the user: "Your CPU and motherboard sockets match perfectly. However, our database cannot verify the exact BIOS revision installed on this board. We recommend confirming with the retailer whether the motherboard BIOS has been flashed to support the 7800X3D out of the box."
Admitting what the system does not know is the hallmark of trustworthy enterprise software. Fabricating certainty to fill a blank space in a UI is technical negligence.
The Three-Zone Systems Model
A rigorous boundary dividing what we know, what we interpret, and what we do not have
What the System Knows
- • Relational database records & primary keys
- • Hard mathematical formulas & arithmetic
- • Cryptographic auth tokens & session IDs
- • Active RBAC role clearance & permissions
- • Validated physical & logical compatibility rules
- • Strict multi-tenant data boundaries (RLS)
What the System Interprets
- • Natural-language intent & query parsing
- • Messy document text classification
- • Multi-message summarization & briefings
- • Semantic vector search & hybrid retrieval
- • Context-aware prose drafting
- • Explanatory narrative over structured evidence
What the System Lacks
- • Missing hardware specifications or clearances
- • Unindexed external documentation
- • Ambiguous temporal terms ("sometime soon")
- • Unspecified currency or regional tax units
- • Telemetry gaps in third-party APIs
- • Actions lacking explicit user authorization
4. The Architectural Responsibility Map
To prevent architectural confusion when designing features across engineering teams, every technical capability in your SaaS platform should have an unambiguous, designated owner.
The table below represents production architectural guidance. While real-world applications often blend these domains, this matrix defines where primary authoritative responsibility must reside:
The Enterprise Architectural Responsibility Map
Designating primary ownership across deterministic systems and probabilistic AI capabilities
| System Capability / Task | Primary Authority | Role of Deterministic Code | Role of AI Layer |
|---|---|---|---|
| Authentication & Identity | Application Code | Validates JWTs, hashes passwords, enforces MFA, cryptographically signs session cookies. | Zero authority. AI must never issue, inspect, or bypass authentication credentials. |
| Authorization & RBAC | Application Code | Evaluates role definitions, checks resource ownership, enforces tenant-scoped isolation. | Zero authority. Cannot grant, elevate, or assume user administrative permissions. |
| Exact Arithmetic & Pricing | Database / Code | Calculates subtotal, discounts, tax rates, currency conversions, and billing balances. | Zero math authority. Explains quotes, drafts proposals, and compares package options. |
| Inventory & Seat Quotas | Database Engine | Enforces atomic decrement, checks live stock levels, prevents double-booking via row locks. | Communicates availability to user; cannot assume an out-of-stock item is available. |
| Booking Availability | Scheduling Engine | Evaluates calendar conflicts, staff shifts, capacity limits, and operating hours. | Parses natural language requests ("Thursday afternoon") and presents verified slots. |
| Compatibility & Constraints | Rule Engine | Validates physical, electrical, and logical rules against structured component catalogs. | Explains technical tradeoffs, bottlenecks, and upgrade balance among valid parts. |
| Intent Understanding | AI Layer | Passes untrusted user strings safely; enforces rate limits and schema extraction gates. | Interprets colloquial language, maps messy user prompts to structured parameter schemas. |
| Text Classification & Triage | AI Layer | Defines strict target enum categories and validates output format via Zod/Pydantic. | Evaluates sentiment, detects urgency, and tags incoming support emails into categories. |
| Narrative Summarization | AI Layer | Retrieves pre-filtered, tenant-scoped records from database to populate prompt context. | Synthesizes 50 log entries or audit trails into concise, actionable executive briefings. |
| Missing Information | UNKNOWN / System | Detects null or unverified fields; halts automatic execution until confirmed. | Explicitly communicates ambiguity to user; prompts for specific missing parameters. |
5. Why LLM Output Varies: Sampling, Checkpoints, and the Impossibility of Guarantees
To understand why foundation models cannot serve as deterministic business logic, engineers must understand how language generation actually operates under the hood.
A generative model produces text by computing a probability distribution over a vocabulary of tokens conditioned on the preceding context. When a response is generated, sampling algorithms—such as Top-p (nucleus sampling), Top-k, and temperature—determine which token is selected from that distribution.
Many developers believe setting temperature = 0 transforms an LLM into a deterministic function. This is an engineering myth.
Even at temperature zero, model outputs across production workloads can vary due to several technical factors:
- Floating-Point Non-Determinism: Modern distributed GPU clusters (NVIDIA H100s, B200s) execute matrix multiplications in parallel using non-associative floating-point operations. The order of parallel CUDA thread reductions can introduce micro-variations in the final logit values, occasionally flipping the highest-ranked token.
- Mixture-of-Experts (MoE) Routing: Contemporary frontier models (such as GPT-4o and Gemini 1.5) employ sparse MoE architectures where different tokens are routed dynamically to different expert sub-networks. Dynamic batching and speculative decoding under varying server loads can subtly shift token paths.
- Silent Upstream Updates: Cloud model providers regularly update system prompts, safety guardrails, quantization schemes, and underlying model weights without changing the API endpoint name.
- Context Sensitivity: A tiny, seemingly irrelevant change in the user prompt—a trailing space, a greeting, or the order of items in a JSON array—can alter attention weights and yield a completely different chain of thought.
Therefore, the engineering heuristic is absolute: Lower sampling variability does not transform a probabilistic text generator into deterministic software. If a business requirement demands that the same inputs must mathematically yield the identical output every time, that requirement must be implemented in code.
6. Reproducibility & Scoring Engine Architecture
Consider what happens when an enterprise customer challenges a business decision:
"Why did our company's credit application receive a score of 68 instead of 75? Why was our vendor discount capped at 12% instead of 18%?"
If the score was generated by an LLM prompted with: "Review this financial profile and give it a credit rating from 1 to 100," your engineering team cannot defend the decision in a legal audit. You cannot explain which variable caused the score to drop. If you run the exact same customer profile through the model five minutes later, it might return a 74.
In contrast, when scoring is governed by a versioned deterministic engine (e.g. credit_scoring_v3.2), the calculation is 100% reproducible and auditable:
- Inputs: Debt-to-income ratio (32%), historical on-time payment rate (98%), cash reserves ($450,000).
- Weights: Payment history (40%), Liquidity (35%), Debt ratio (25%).
- Score Output: 68.4 / 100.
The Hybrid Pattern: AI Explains the Engine
Does this mean AI has no place in scoring systems? On the contrary! The most powerful hybrid pattern in modern SaaS architecture is: The deterministic engine computes the score; the AI explains the score.
The application passes the structured score breakdown to the LLM:
{
  "engine_version": "build_score_v1",
  "overall_score": 78,
  "factors": {
    "workload_gaming_1440p": { "score": 28, "max": 30, "status": "EXCELLENT" },
    "cpu_gpu_balance": { "score": 24, "max": 25, "status": "BALANCED" },
    "upgrade_flexibility": { "score": 14, "max": 25, "status": "CONSTRAINED", "bottleneck": "Motherboard has only 2 RAM slots and single Gen4 M.2 slot" },
    "power_efficiency": { "score": 12, "max": 20, "status": "SUFFICIENT", "headroom_watts": 85 }
  }
}
The AI generates the explanation:
"Your build achieved an overall score of 78/100. It offers outstanding 1440p gaming performance with optimal CPU-to-GPU balance. However, your score is primarily constrained by the motherboard's upgrade flexibility: with only two memory slots and a single Gen4 M.2 port, future storage and RAM expansions will require replacing existing components rather than adding new ones."
Notice the critical architectural distinction: The AI explains the engine's verified factors; it does not secretly invent them. If the user asks why the score is 78, the explanation directly mirrors the mathematical reality of the system.
The Structured Evidence Packet
How deterministic engine calculations are safely handed off to the AI interpretation layer
{
  "build_id": "pc_cfg_9921",
  "compatibility": {
    "socket": { "status": "PASS", "value": "AM5" },
    "memory": { "status": "PASS", "gen": "DDR5" },
    "psu_headroom": { "status": "PASS", "watts": 180 },
    "bios_firmware": { "status": "UNKNOWN", "note": "Board rev unverified" }
  },
  "score": {
    "overall": 82,
    "gaming_1440p": 28,
    "upgrade_headroom": 16
  }
}
VERIFIED Socket & Memory: Your Ryzen 7 7800X3D and Corsair DDR5 memory are fully verified compatible with the AM5 platform.
WARNING Upgrade Flexibility: The build scores 82/100. While 1440p gaming performance is top-tier (28/30), motherboard expansion lanes constrain future secondary NVMe drives.
UNKNOWN BIOS Version: Factory BIOS support cannot be confirmed from available catalog data; verify firmware revision prior to assembly.
7. Real-World Business Workflows: Where the Boundary Lies
To demonstrate how this architecture applies across diverse software industries, let us examine eight core business workflows where naive AI integration causes disaster, and how defensive engineering solves them:
1. Pricing & Quotations
In B2B SaaS, pricing is determined by explicit contractual tiers: Base subscription ($10,000) + Additional Seats ($2,000) - Approved Partner Discount ($1,000) + 14% VAT.
Bad Architecture: Passing customer notes to an LLM and prompting: "Calculate a fair price quote for this customer." The model invents arbitrary numbers that violate corporate margin guidelines.
Good Architecture: The deterministic pricing engine computes subtotal, discounts, and taxes. The AI drafts the commercial cover letter, explains the package features, and compares tier benefits. The AI never computes prices.
2. Discounts & Sales Delegation
A company policy dictates: "Account Executives can offer up to a 15% discount. Sales Directors can approve up to 25%. Any discount over 25% requires VP of Finance approval."
Bad Architecture: Adding a prompt instruction: "Please make sure you never propose a discount greater than 20%." A prompt injection or persuasive user query can easily manipulate the LLM into offering 40%.
Good Architecture: The AI may propose a discount based on customer negotiation history. But before the proposal can be committed or displayed as an official offer, backend middleware validates: proposed_discount <= user.authorized_discount_limit. If the limit is exceeded, the mutation is hard-rejected by code. Prompts guide behavior; code enforces invariants.
3. Role-Based Access Control (RBAC)
As explored in Building Role-Based Access Control for Modern SaaS Platforms, authorization must be enforced strictly in application middleware.
Bad Architecture: Prompting an LLM: "The user wants to delete project #41. Is this user authorized as an admin?"
Good Architecture: The application extracts the user's verified cryptographic session, checks permissions against the database, and only presents valid actions to the user. The AI operates within an already-authorized context. Authorization must never depend on model judgment.
4. Multi-Tenant Data Isolation
In How to Design a Multi-Tenant SaaS Platform Without Mixing Customer Data, we detailed the severe risks of cross-tenant leakage.
Bad Architecture: Injecting documents from multiple tenants into a vector store and telling the model: "Only retrieve and talk about Tenant A." Prompt jailbreaks can easily trick the model into revealing Tenant B's data.
Good Architecture: Every vector retrieval and SQL query enforces WHERE tenant_id = $1 at the database level before data ever touches the LLM prompt. The model is never your tenant firewall.
5. Calendar Booking & Scheduling
A user types into a clinic portal: "Book me an appointment with Dr. Sarah sometime Thursday afternoon."
Bad Architecture: The LLM hallucinates: "You are booked for Thursday at 3:30 PM!" without querying the scheduling database. When the patient arrives, the clinic is closed or double-booked.
Good Architecture: The AI extracts the structured intent: { practitioner: "Dr. Sarah", date: "2026-10-01", window: "afternoon" }. The scheduling engine queries the database for actual available slots: [14:00, 15:30, 16:15]. The AI presents these verified choices to the user. When the user confirms, an atomic database transaction secures the slot.
6. Inventory & Order Fulfillment
A customer asks an e-commerce assistant: "Can I order 5 units of the industrial water filter right now?"
Bad Architecture: The model reads a cached product description that says "In Stock" and promises immediate dispatch.
Good Architecture: The inventory engine executes a live row-locked query: SELECT stock_quantity FROM inventory WHERE sku = 'WF-100'. It returns 3. The AI explains: "We currently have only 3 units in stock for immediate shipment. Would you like to ship the 3 available units today and backorder the remaining 2?" Facts originate from live state.
7. Payroll & Compensation
An HR SaaS includes an employee portal.
Bad Architecture: Prompting an AI to "calculate net salary after income taxes, social insurance, and overtime."
Good Architecture: The payroll engine computes exact gross-to-net pay according to statutory national tax tables. The AI explains the payslip: "Your net pay reflects 6 hours of approved weekend overtime, offset by the annual social insurance contribution bracket adjustment implemented this month."
8. Support Ticket Escalation & Priority
How should a customer support platform prioritize tickets?
Bad Architecture: Pure rules (cannot detect customer tone or subtle operational crises) OR pure AI (might deprioritize an enterprise client because the email was written politely).
Good Architecture (Rules + AI Signal):
- Hard Deterministic Rules: If the client is a Tier-1 Enterprise account or if an active service outage is detected, priority is automatically locked to
HIGHorCRITICAL. - AI Semantic Signal: The LLM analyzes the text to detect frustration sentiment and semantic urgency (e.g. "data loss threat detected").
- Combined Decision: The decision engine evaluates:
final_priority = max(hard_tier_priority, ai_urgency_signal). The AI can elevate priority based on nuance, but it can never downgrade a mandatory business priority.
Hard Constraints vs Soft Signals
How high-reliability systems bound probabilistic interpretation with non-negotiable rules
Enforced Absolutely by Code
Conditions that must never be violated under any circumstance, regardless of user prompt persuasion or model output:
- 🔒 RBAC Permissions: User clearance and tenant isolation.
- 💰 Budget & Discount Ceilings: Maximum allowable price drops.
- 🔌 Physical Compatibility: Socket, pinout, voltage limits.
- 📦 Inventory Availability: Atomic stock levels in database.
- ⚖️ Legal & Regulatory Rules: Data residency and compliance policies.
Evaluated Intelligently by AI
Subjective preferences, contextual tradeoffs, and qualitative priorities that guide choices among valid options:
- 🎨 Aesthetic Preference: Component color matching, case styling.
- 🎯 Workload Alignment: Gaming vs video editing vs CAD balance.
- 📈 Upgrade Philosophy: Budget-saving now vs future-proofing.
- 💬 Sentiment & Tone: Frustration level in customer inquiries.
- 🔍 Semantic Relevance: Conceptual similarity in document search.
8. Architectural Patterns: The Deterministic Shell & The AI Sandwich
How do these principles translate into concrete software architecture? In production systems, two complementary architectural patterns predominate:
Pattern 1: The Deterministic Shell Around a Probabilistic Core
In this pattern, the application surrounds the AI capability with rigid validation and security wrappers. The model is treated as a sensitive internal processing core that is never directly exposed to raw external user requests or direct database write operations:
The Deterministic Shell Pattern
Isolating probabilistic inference within a rigid, deterministic security and validation harness
Pattern 2: The "AI Sandwich" (AI $\rightarrow$ Code $\rightarrow$ AI)
The inverse pattern is the AI Sandwich—an intuitive structure for building natural-language interfaces over authoritative business systems:
- Top Layer (AI - Understand): The user provides unstructured, conversational input. The AI parses the request and compiles it into a strongly typed, structured intent object.
- Middle Layer (Code - Execute): The deterministic backend receives the structured intent, validates permissions, checks hard constraints, queries authoritative tables, and computes exact mathematical results.
- Bottom Layer (AI - Explain): The AI receives the verified results and translates them back into a fluent, conversational narrative for the user.
The "AI Sandwich" Pattern: AI → Code → AI
Converting messy natural language into verified transactional truth and back into clear human narrative
"What does the user want?"
User types: "Find me gaming laptops under 45k EGP with at least 16GB RAM available in Alexandria today." AI parses this into typed parameters: { category: "laptop", max_price: 45000, min_ram: 16, city: "Alexandria", in_stock: true }.
"What is true, available, and allowed?"
SQL query executes against the inventory database with exact price and stock filters. The database returns exactly 2 matching laptop models in stock at the Alexandria hub. Zero hallucinated inventory.
"How do we explain the results?"
AI receives the 2 verified laptops and generates a friendly comparison highlighting display refresh rates and battery life tradeoffs.
9. The Four Validation Layers for AI Outputs
When an LLM produces structured output (such as JSON generated via OpenAI structured outputs, Anthropic tool calls, or instructor schemas), software engineers often assume the data is safe to consume.
This is a critical oversight. A JSON object can be syntactically valid while being semantically absurd or commercially dangerous. Production systems evaluate AI outputs through Four Validation Layers:
The Four-Layer AI Output Validation Pipeline
Every generated payload must pass all four gates before touching application state
Structural Validation
Is the output valid JSON conforming to the expected Zod/Pydantic schema? Are required keys present? Are data types correct?
Catches: Malformed JSON, missing fieldsDomain Validation
Do values fall within acceptable domain ranges? Are percentages between 0 and 100? Are enum values members of the allowed set?
Catches: Discount = 450%, Unknown categoriesBusiness Validation
Does the proposed value satisfy company business rules? Is the discount within the sales rep's ceiling? Is the requested item compatible?
Catches: Discount > 20%, Incompatible partsAuthorization Validation
Does the active user have permission to execute this specific mutation on this resource? Does the referenced entity belong to their tenant?
Catches: Cross-tenant IDs, Privilege escalationConsider this concrete code example:
// Runtime validation of model-proposed discount
export async function validateAiProposedDiscount(
  tenantId: string,
  user: AuthenticatedUser,
  rawModelOutput: unknown
) {
  // Layer 1: Structural Validation
  const schema = z.object({
    dealId: z.string().uuid(),
    discountPercentage: z.number()
  });
  const parsed = schema.safeParse(rawModelOutput);
  if (!parsed.success) {
    throw new ValidationError("Model output violated structural schema.");
  }

  // Layer 2: Domain Validation
  const { dealId, discountPercentage } = parsed.data;
  if (discountPercentage < 0 || discountPercentage > 100) {
    throw new DomainError("Discount percentage must be between 0 and 100.");
  }

  // Layer 3: Business Validation
  const maxAllowed = user.role === 'DIRECTOR' ? 25 : 15;
  if (discountPercentage > maxAllowed) {
    throw new BusinessRuleError(`Proposed discount of ${discountPercentage}% exceeds user limit of ${maxAllowed}%.`);
  }

  // Layer 4: Authorization & Tenant Validation
  const deal = await db.deal.findFirst({
    where: { id: dealId, tenantId: tenantId }
  });
  if (!deal) {
    throw new SecurityError("Deal not found or does not belong to authorized tenant.");
  }

  return { deal, authorizedDiscount: discountPercentage };
}
10. State Machines & Finite Transitions: Taming Autonomous Side Effects
One of the most consequential risks of integrating AI into SaaS products is granting models the ability to trigger external side effects: sending emails, issuing refunds, changing pipeline stages, or deleting records.
In enterprise applications, workflows are governed by Finite State Machines (FSMs). An invoice moves predictably from DRAFT $\rightarrow$ SUBMITTED $\rightarrow$ APPROVED $\rightarrow$ PAID.
An LLM should never be allowed to arbitrarily transition an entity from DRAFT directly to PAID simply because a user typed: "Mark this invoice as completed."
The state machine defines the only valid transitions. The AI merely acts as an interpreter identifying the user's desired transition:
State Machine Governed AI Transitions
How deterministic finite state machines prevent unauthorized workflow jumps
11. Defensive Testing: How to Test Systems That Combine Rules and AI
Testing a system that combines deterministic logic with probabilistic models requires two fundamentally different testing strategies:
1. Unit & Invariant Testing for Deterministic Logic
Your deterministic rules must have comprehensive automated unit and property-based test suites. You do not need an LLM to test whether DDR4 memory fails on an AM5 motherboard. You write pure, millisecond-fast unit tests:
describe("CompatibilityEngine", () => {
  it("rejects DDR4 memory on AM5 motherboards", () => {
    const result = checkMemoryCompatibility(am5Motherboard, ddr4Ram);
    expect(result.status).toBe("FAIL");
    expect(result.reason).toContain("DDR5 required");
  });

  it("never allows discounts exceeding 25% for sales directors", () => {
    expect(() => validateDiscount(salesDirector, 26)).toThrow(BusinessRuleError);
  });
});
2. Boundary & Mock Fuzz Testing for the AI Gateway
Never assume the LLM will output well-formed data in production. In your automated test suite, deliberately feed your validation pipeline malicious, truncated, and impossible model outputs:
- Test what happens when the LLM outputs a negative discount percentage (
-50%). - Test what happens when the LLM outputs a customer ID belonging to another tenant.
- Test what happens when the LLM invents a non-existent hardware category (
liquid_nitrogen_chiller). - Test what happens when the LLM returns an empty JSON payload or markdown fences.
Your application must safely intercept and reject every single one of these anomalies without throwing 500 server errors or corrupting the database.
3. Evaluation Rubrics for the AI Layer
For the AI layer itself, replace brittle exact-string tests with automated evaluation rubrics:
- Contradiction Tests: If the deterministic engine outputs
in_stock: false, does the AI explanation ever state or imply the item is available? (If yes $\rightarrow$ Fail eval). - Unknown State Preservation Tests: If the evidence packet marks
bios_version: UNKNOWN, does the AI preserve the uncertainty or does it falsely claim compatibility? (If it fabricates certainty $\rightarrow$ Fail eval).
12. The Architectural Decision Tree
Whenever your engineering team is evaluating whether a new feature or sub-task should be solved with deterministic software or an AI capability, run the task through this architectural decision tree:
The Architectural Decision Tree: Code vs AI
A systematic framework for routing responsibilities across system layers
Is there an exact rule, formula, or database truth?
Tax formulas, inventory counts, socket matching, permissions, session tokens.
Do not involve the LLM.
Does the task require interpreting unstructured data?
Freeform user text, multi-page PDFs, sentiment, summaries, conversational intent.
Extract to typed schema.
Is essential decision data missing from the system?
Unverified firmware, unindexed documentation, ambiguous temporal timeframes.
Prompt user for clarification.
Does model output trigger a state mutation?
Updating a deal, issuing a refund, modifying a firewall rule, creating records.
Human confirm + Atomic commit.
13. Strategic Summary: The Golden Rules of Deterministic Logic + AI
Great software engineering is not about choosing between artificial intelligence and traditional programming. It is about architectural discipline: assigning each component the exact responsibility it is mathematically equipped to handle.
To build reliable, enterprise-grade AI systems, remember these fundamental axioms:
- Use code for what you know. Use AI for what you need to interpret. Never ask an LLM to guess a rule that your software already knows how to check.
- Calculators must calculate. Pass verified numbers and database metrics into the prompt as immutable facts; let the model articulate what the numbers mean.
- Preserve the UNKNOWN state. Do not force missing data into probabilistic model inference just to fill a screen. Admitting what your system does not know builds enterprise credibility.
- Prompts guide behavior; code enforces invariants. Never rely on system prompts as an authorization firewall, a tenant boundary, or a financial discount ceiling. Enforce all invariants in deterministic middleware.
- Separate model updates from business truth. Upgrading from Claude 3.5 to Claude 4, or from GPT-4o to GPT-5, should refine your explanations and improve semantic nuance—it must never alter your product prices, violate your RBAC rules, or break hardware compatibility.
When you anchor your software in deterministic truth and wrap it in the intelligent capabilities of modern AI, you build applications that are both profoundly capable and unshakeably reliable.
Planning to Implement AI Agents or Modern Automation?
Bridging deterministic business workflows with autonomous AI agents requires rigorous architectural boundaries, tool encapsulation, rate limits, and human-in-the-loop oversight. Kamashka designs and builds production-grade, reliable AI and software automation systems.
The Production AI Architecture & Engineering Series
A 5-part engineering series exploring agent autonomy boundaries, pragmatic SaaS integration, deterministic safeguards, operational reliability, and architectural choices.
An architectural guide evaluating deterministic workflows vs agentic decision loops, error cost matrices, and autonomy budgets.
An architectural guide to integrating AI while preserving deterministic business rules, tenant boundaries, and RBAC security.
Why production systems enforce deterministic business rules around probabilistic models, the Three-Zone model, and the AI Sandwich pattern.
Architecting for API outages, tiered model cascades, graceful degradation, and idempotency in AI pipelines.
A pragmatic architectural guide evaluating retrieval, specialized fine-tuning, prompt engineering, and live tools.